mirror of
https://github.com/AAndyProgram/SCrawler.git
synced 2026-11-10 13:45:25 +00:00
2026.9.21.0
 Andy
1
Home.md
1
Home.md
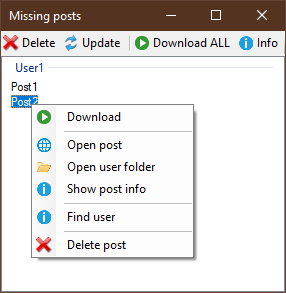
@@ -71,6 +71,7 @@ Context menu:
|
|||||||
|
|
||||||
Hot keys:
|
Hot keys:
|
||||||
- `F1` - `Info`
|
- `F1` - `Info`
|
||||||
|
- `ESC` - close form
|
||||||
|
|
||||||
|

|
||||||
|
|
||||||
|
|||||||
32
Settings.md
32
Settings.md
@@ -111,6 +111,7 @@
|
|||||||
- `After download cmd` - this [command](#scrawler-script-text-examples) will be executed after all downloads are completed
|
- `After download cmd` - this [command](#scrawler-script-text-examples) will be executed after all downloads are completed
|
||||||
- `Add missing information to log` - Text will be added to the log stating that the [missing posts](https://github.com/AAndyProgram/SCrawler/wiki/#missing-posts) exist.
|
- `Add missing information to log` - Text will be added to the log stating that the [missing posts](https://github.com/AAndyProgram/SCrawler/wiki/#missing-posts) exist.
|
||||||
- `Add missing errors to log` - Each error that prevents SCrawler from downloading a file will be added to the log.
|
- `Add missing errors to log` - Each error that prevents SCrawler from downloading a file will be added to the log.
|
||||||
|
- `Add 'missing' users to log` - add information to the log about users who have missing posts. This means that the list of user (who have missing posts) will be added to the log.
|
||||||
- `Trying to download missing posts using regular download` - If missing posts exist, the missing posts will attempt to be downloaded via user download.
|
- `Trying to download missing posts using regular download` - If missing posts exist, the missing posts will attempt to be downloaded via user download.
|
||||||
- `Use the default account if the selected account does not exist` - Use the default account if you deleted an account that you used for some users.
|
- `Use the default account if the selected account does not exist` - Use the default account if you deleted an account that you used for some users.
|
||||||
- `Highlight undownloaded plans (minutes)` - Highlight (in gray) the scheduler plans that have not been downloaded in `x` minutes. `-1` to disable.
|
- `Highlight undownloaded plans (minutes)` - Highlight (in gray) the scheduler plans that have not been downloaded in `x` minutes. `-1` to disable.
|
||||||
@@ -167,7 +168,6 @@ Red highlight means that the field is required or you have entered an incorrect
|
|||||||
- [Twitter](#twitter-requirements)
|
- [Twitter](#twitter-requirements)
|
||||||
- [Bluesky](#bluesky-requirements)
|
- [Bluesky](#bluesky-requirements)
|
||||||
- [OnlyFans](#onlyfans-requirements)
|
- [OnlyFans](#onlyfans-requirements)
|
||||||
- [Mastodon](#mastodon-requirements)
|
|
||||||
- [Instagram](#instagram-requirements)
|
- [Instagram](#instagram-requirements)
|
||||||
- [Threads](#threads-requirements)
|
- [Threads](#threads-requirements)
|
||||||
- [Facebook](#facebook-requirements)
|
- [Facebook](#facebook-requirements)
|
||||||
@@ -222,6 +222,8 @@ ffmpeg is required for several sites like Reddit, PornHub, XHamster, XVIDEOS, et
|
|||||||
- [xHamster](#xhamster)
|
- [xHamster](#xhamster)
|
||||||
- [XVIDEOS](#xvideos)
|
- [XVIDEOS](#xvideos)
|
||||||
|
|
||||||
|
and some modules...
|
||||||
|
|
||||||
### Gallery-dl
|
### Gallery-dl
|
||||||
**[GitHub releases](https://github.com/mikf/gallery-dl/releases), [Codeberg releases](https://codeberg.org/mikf/gallery-dl/releases)**
|
**[GitHub releases](https://github.com/mikf/gallery-dl/releases), [Codeberg releases](https://codeberg.org/mikf/gallery-dl/releases)**
|
||||||
<!--
|
<!--
|
||||||
@@ -244,6 +246,7 @@ Version **2025.09.05** ([release](https://github.com/yt-dlp/yt-dlp/releases/tag/
|
|||||||
- [YouTube](#youtube)
|
- [YouTube](#youtube)
|
||||||
- [ThisVid](#thisvid)
|
- [ThisVid](#thisvid)
|
||||||
- [TikTok](#tiktok)
|
- [TikTok](#tiktok)
|
||||||
|
- [PornHub](#pornhub)
|
||||||
- [xHamster](#xhamster)
|
- [xHamster](#xhamster)
|
||||||
|
|
||||||
### OF-Scraper
|
### OF-Scraper
|
||||||
@@ -461,33 +464,6 @@ Other settings **(change these values only if you know what you are doing)**
|
|||||||
|
|
||||||
**No! SCrawler is not a hacking program. Just a downloader.**
|
**No! SCrawler is not a hacking program. Just a downloader.**
|
||||||
|
|
||||||
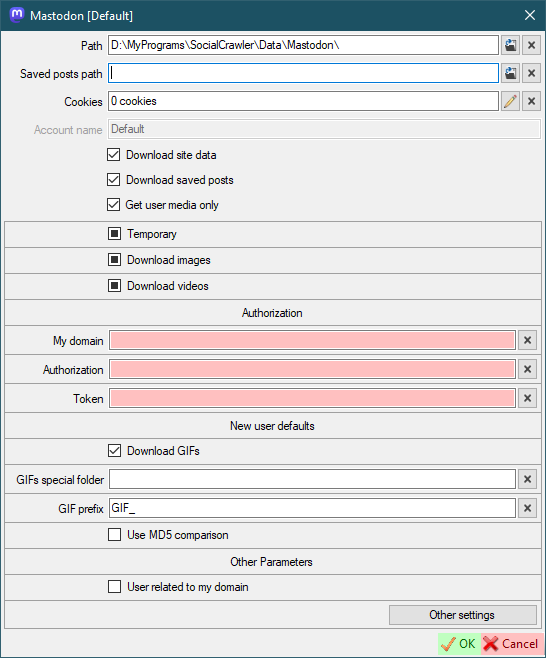
## Mastodon
|
|
||||||
- Authorization
|
|
||||||
- `My Domain` - your account domain without `https://` (for example, `mastodon.social`)
|
|
||||||
- `Authorization` - `Authorization` request header. Must start with `Bearer ` word. [How to find](#how-to-find-headers).
|
|
||||||
- `Token` - `x-csrf-token` request header. [How to find](#how-to-find-headers).
|
|
||||||
- New user defaults
|
|
||||||
- `Download GIFs` - *(default for new users) this can also be configured for a specific user.*
|
|
||||||
- `GIFs special folder` - *(default for new users)* Put the GIFs in a special folder. **This is a folder name, not an absolute path** (examples: `SomeFolderName`, `SomeFolderName\SomeFolderName2`). This folder(s) will be created relative to the user's root folder. *This can also be configured for a specific user.*
|
|
||||||
- `GIF prefix` - *(default for new users)* This prefix will be added to the beginning of the filename. *This can also be configured for a specific user.*
|
|
||||||
- `Use MD5 comparison` - *(default for new users)* each image will be checked for existence using MD5 (this may be suitable for the users who post the same image many times). *This can also be configured for a specific user.*
|
|
||||||
- Other parameters
|
|
||||||
- `User related to my domain` - open user profiles and user posts through my domain.
|
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
### Mastodon requirements
|
|
||||||
- `My Domain`
|
|
||||||
- [`Authorization`](#how-to-find-headers)
|
|
||||||
- [`Token`](#how-to-find-headers)
|
|
||||||
- [`Authorization`](#how-to-find-headers) and [`Token`](#how-to-find-headers) for each domain you want to download from (see [additional settings](#Mastodon-additional-setting))
|
|
||||||
|
|
||||||
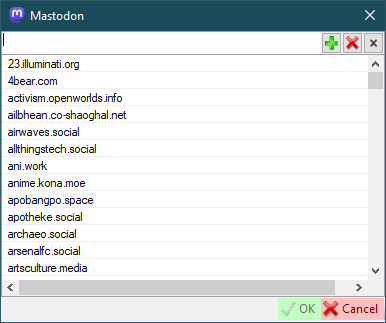
### Mastodon additional setting
|
|
||||||
|
|
||||||
To support the downloading of this site you should add the Mastodon domain to this list.
|
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
## Instagram
|
## Instagram
|
||||||
- Authorization
|
- Authorization
|
||||||
- `x-csrftoken` - [how to find](#how-to-find-headers) *(can be automatically extracted from cookies)*
|
- `x-csrftoken` - [how to find](#how-to-find-headers) *(can be automatically extracted from cookies)*
|
||||||
|
|||||||
Reference in New Issue
Block a user